

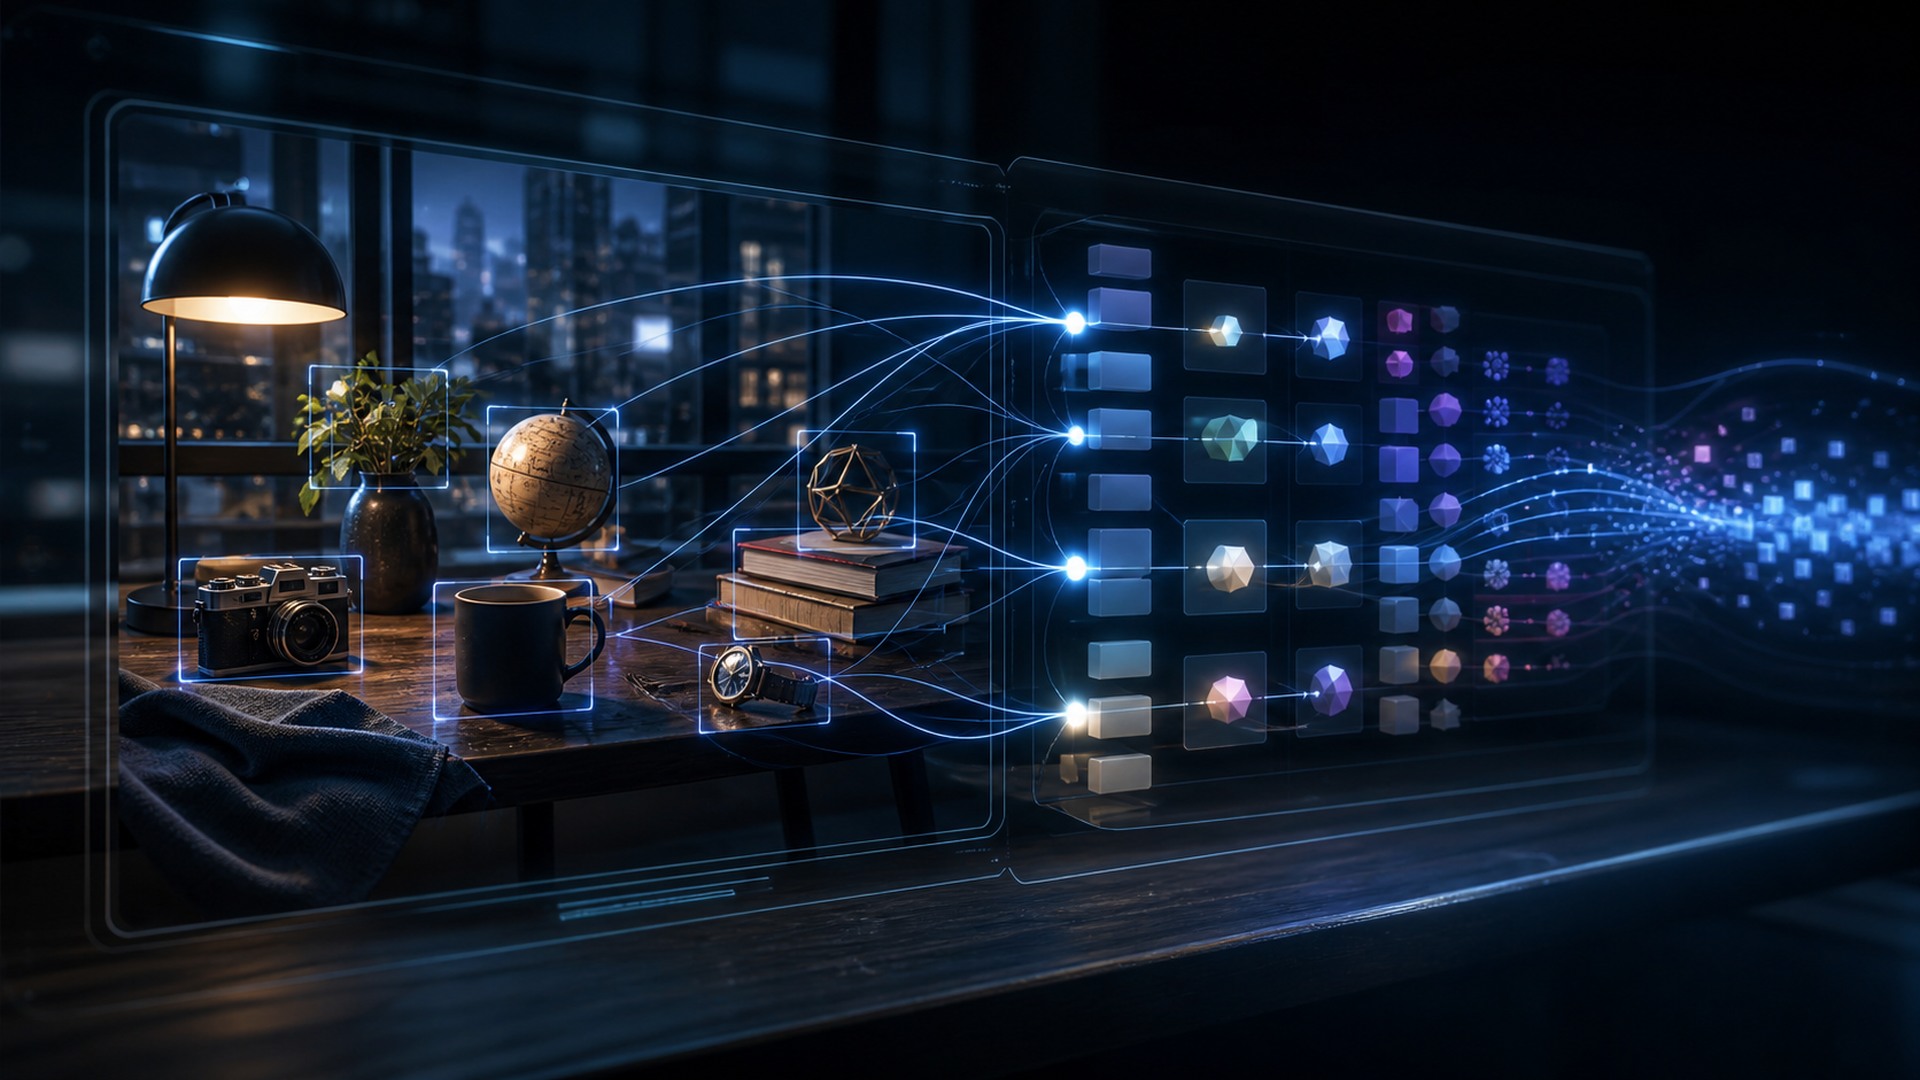
Vision-language models connect visual features with language so a system can describe, compare, retrieve, or reason about images using words.
Vision-language models deserves a precise explanation because its name identifies a particular information flow, training choice, runtime mechanism, or governance boundary. Treating it as a synonym for “advanced AI” makes claims impossible to test. This guide follows the concept from its input and assumptions through its observable result, then tests the shortcut most likely to be confused with it.
Vision-Language Models: Definition, Boundary, and Purpose
Vision-language models connect visual features with language so a system can describe, compare, retrieve, or reason about images using words. The definition contains three practical commitments: there is an identifiable input, a transformation or decision that is characteristic of Vision-language models, and an outcome that can be evaluated against a stated objective. If one of those elements is missing, the label may describe an aspiration rather than an implemented mechanism.
Multimodal systems must align signals that have different resolutions, timing, noise, and ambiguity. A word may refer to a small image region; an audio event may precede the video frame that explains it. For Vision-language models, this system view matters because performance can be determined by the surrounding data, interfaces, hardware, permissions, and people even when the underlying model is unchanged. A useful explanation therefore separates the model’s learned behavior from the product that decides when, where, and with what authority that behavior is used.
The nearest misleading shortcut is computer vision that predicts a fixed label without open-ended language. It may share a visible feature with Vision-language models, yet it changes the causal story: different evidence would establish success, different reharm. The boundary is therefore operational rather than terminological
A Five-Stage Operating Map of Vision-Language Models
The diagram is a compact causal map for Vision-language models, not a claim that every implementation uses five software components. Some systems combine stages and others repeat them in a loop. The map remains useful because it forces each change in information or authority to have an owner, an input, an output, and a test.
1. Divide or Encode the Image into Visual Tokens: Input and Assumptions in Vision-Language Models
At this stage of Vision-language models, the system must divide or encode the image into visual tokens. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from computer vision that predicts a fixed label without open-ended language and reproduce its result under the same stated conditions.
The handoff into this Vision-language models stage begins with the stated objective and should end with a result that can support encode the accompanying text. Record uncertainty, rejected alternatives, rery. That trace is where teams can detect whether fluent descriptions can name objects or relationships that are not actually visible before the same weakness reaches a consequential output
2. Encode the Accompanying Text: Representation or Decision in Vision-Language Models
At this stage of Vision-language models, the system must encode the accompanying text. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from computer vision that predicts a fixed label without open-ended language and reproduce its result under the same stated conditions.
The handoff into this Vision-language models stage begins with divide or encode the image into visual tokens and should end with a result that can support connect both representations. Record uncertainty, rejected alternatives, rery. That trace is where teams can detect whether fluent descriptions can name objects or relationships that are not actually visible before the same weakness reaches a consequential output
3. Connect Both Representations: Distinctive Transformation in Vision-Language Models
At this stage of Vision-language models, the system must connect both representations. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from computer vision that predicts a fixed label without open-ended language and reproduce its result under the same stated conditions.
The handoff into this Vision-language models stage begins with encode the accompanying text and should end with a result that can support attend across regions and phrases. Record uncertainty, rejected alternatives, rery. That trace is where teams can detect whether fluent descriptions can name objects or relationships that are not actually visible before the same weakness reaches a consequential output
4. Attend Across Regions and Phrases: Constraint and Verification Boundary in Vision-Language Models
At this stage of Vision-language models, the system must attend across regions and phrases. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from computer vision that predicts a fixed label without open-ended language and reproduce its result under the same stated conditions.
The handoff into this Vision-language models stage begins with connect both representations and should end with a result that can support decode a grounded response or action. Record uncertainty, rejected alternatives, rery. That trace is where teams can detect whether fluent descriptions can name objects or relationships that are not actually visible before the same weakness reaches a consequential output
5. Decode a Grounded Response or Action: Output, Feedback, and Stop Rule in Vision-Language Models
At this stage of Vision-language models, the system must decode a grounded response or action. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from computer vision that predicts a fixed label without open-ended language and reproduce its result under the same stated conditions.
The handoff into this Vision-language models stage begins with attend across regions and phrases and should end with a result that can support monitoring or a final decision. Record uncertainty, rejected alternatives, rery. That trace is where teams can detect whether fluent descriptions can name objects or relationships that are not actually visible before the same weakness reaches a consequential output
Read the Vision-language models map forward to understand production and backward to diagnose failure. Forward analysis asks how one stage supplies the next. Backward analysis starts from an incorrect, slow, expensive, or unsafe result and traces which earlier assumption allowed it. The reverse path is often where a team discovers that the decisive error occurred before the model produced anything.
A Worked Vision-Language Models Example
A VLM can inspect a dashboard screenshot and explain which chart supports a written claim.
This example is informative because Vision-language models can be tied to observable inputs, intermediate states, and an outcome rather than judged through a polished demonstration. A rigorous test would build ordinary, difficult, and deliberately misleading cases around the scenario, preserve a baseline without the technique, and record both average performance and the severity of individual failures.
Change one assumption in the Vision-language models example and repeat the analysis. Remove a required input, introduce a conflicting signal, limit compute, alter the user population, or force the system to abstain. A mechanism that only succeeds under one carefully arranged demonstration has not established that it generalizes to the operating environment.
Vision-Language Models vs. Its Most Common Shortcut
Vision-language models is often reduced to computer vision that predicts a fixed label without open-ended language. That reduction removes the very boundary that defines the concept. It can lead buyers to compare unlike products, researchers to overstate what an experiment demonstrates, and operators to monitor the wrong signal after deployment.
| Lens | Practical answer |
|---|---|
| Definition | Vision-language models connect visual features with language so a system can describe, compare, retrieve, or reason about images using words. |
| Confusion | computer vision that predicts a fixed label without open-ended language. |
| Risk | fluent descriptions can name objects or relationships that are not actually visible. |
The comparison should also identify the unit of analysis. A paper about Vision-language models may isolate a model or algorithm, while a deployed service adds retrieval, routing, caching, policy, identity, user interfaces, and monitoring. Two products can use the same headline term while implementing different parts of that stack. Ask which component performs the defining transformation and which other components are necessary for the reported outcome.
Why Vision-Language Models Matters in Current AI Systems
Vision-language models matters now because AI systems are being given larger contexts, more modalities, more runtime compute, broader tool access, and deeper connections to organizational decisions. Under those conditions, what once looked like a research detail can determine latency, security, accessibility, environmental cost, product quality, or legal accountability.
The relevant measure is not whether Vision-language models can produce one impressive result. It is whether the technique improves an outcome that matters across representative conditions and does so more effectively than a simpler baseline. Report distributions, failure categories, tail latency, result into one average
Evaluation should isolate each modality, test conflicting inputs, and verify temporal or spatial grounding. A fluent cross-modal answer is not evidence that the model attended to the right signal. Applied specifically to Vision-language models, that discipline makes the evidence portable: another team can judge whether the claimed gain is likely to survive a different model, language, hardware platform, dataset, user population, or risk tolerance.
Benefits Vision-Language Models Can Deliver
The strongest reason to use Vision-language models is that it can address its intended bottleneck directly. Depending on the implementation, the benefit may appear as better grounding, a more faithful representation, improved generalization, lower latency, reduced memory movement, clearer accountability, or a safer boundary between a model proposal and a real action.
Benefits should be expressed as decisions and measurements. “More intelligent” is not an acceptance criterion for Vision-language models. A useful target might specify error rate on hard cases, recovery after conflicting evidence, cost at a percentile of traffic, human-review time, calibration, or the percentage of actions kept within a defined authority limit.
The Failure Mode That Defines Vision-Language Models
The central limitation is that fluent descriptions can name objects or relationships that are not actually visible. This failure is not an afterthought to list once development is complete. It should shape data collection, architecture, permissions, evaluation, release gates, and monitoring for Vision-language models from the beginning.
A control for Vision-language models is useful only if it acts before an expensive or irreversible consequence. Identify the earliest observable precursor to the failure, set a threshold or rule, assign an accountable owner, and test recovery. Depending on the use case, recovery may mean abstaining, falling back to a simpler system, requesting more evidence, escalating to a person, rolling back a model, or stopping an action entirely.
An Evaluation Plan for Vision-Language Models
Begin evaluation of Vision-language models by writing the decision the evidence must support. Define the operating population, consequence of a wrong result, information actually available at decision time, and the simplest credible alternative. This prevents a benchmark from becoming the goal simply because it is easy to run.
Use an untouched test set for controlled comparisons, then validate Vision-language models in a staged operating environment. Offline evaluation makes variants comparable; shadow mode, canaries, rate limits, or approval gates reveal how real traffic, feedback loops, and people change behavior. The deployment stage should have an explicit stop condition rather than assuming every improvement deserves full rollout.
Version the inputs needed to reproduce Vision-language models:nfiguration, prompt or policy, retrieval index, evaluation set, hardware assumptions, and serving code as applicable. Without lineage, a team cannot tell whether a changed result came from the technique, the environment, or an unnoticed pipeline edit
Finally, ask what finding would falsify the claim that Vision-language models helps. If no result could reverse the adoption decision, the evaluation is marketing. Precommitted acceptance thresholds and a preserved confirmation set turn the exercise into evidence.
Questions to Ask Before Adopting Vision-Language Models
- Objective: Which measurable bottleneck is Vision-language models intended to solve?
- Mechanism: Which of the five stages contains the distinctive transformation?
- Baseline: How does it compare with computer vision that predicts a fixed label without open-ended language or another simpler alternative?
- Evidence: Which ordinary, difficult, adversarial, and subgroup cases were tested?
- Operations: What latency, memory, compute, energy, maintenance, and review costs appear at scale?
- Risk: How will the team detect that fluent descriptions can name objects or relationships that are not actually visible?
- Recovery: Can the system abstain, fall back, roll back, or escalate before harm?
Primary
Authoritative starting points for the part of the AI stack surrounding Vision-language models include CLIP research paper, PaLM-E embodied multimodal model. Read them alongside the documentation for the exact model, dataset, hardware, and jurisdiction involved. A generalnce can establish that a particular implementation is suitable
What to Remember About Vision-Language Models
Vision-language models is a defined mechanism inside a larger sociotechnical system. Its value comes from improving a specific outcome under explicit conditions, not from the label itself. The five-stage map makes its information flow visible, the comparison identifies what it is not, and the control path shows where a responsible operator can intervene.
The practical rule for Vision-language models is to define the objective, compare against a credible baseline, test the failure that matters most, and retain the evidence needed to monitor change. With those pieces in place, the concept becomes an engineering and governance choice that can be evaluated. Without them, it remains a promising name attached to an unknown operating risk.
