

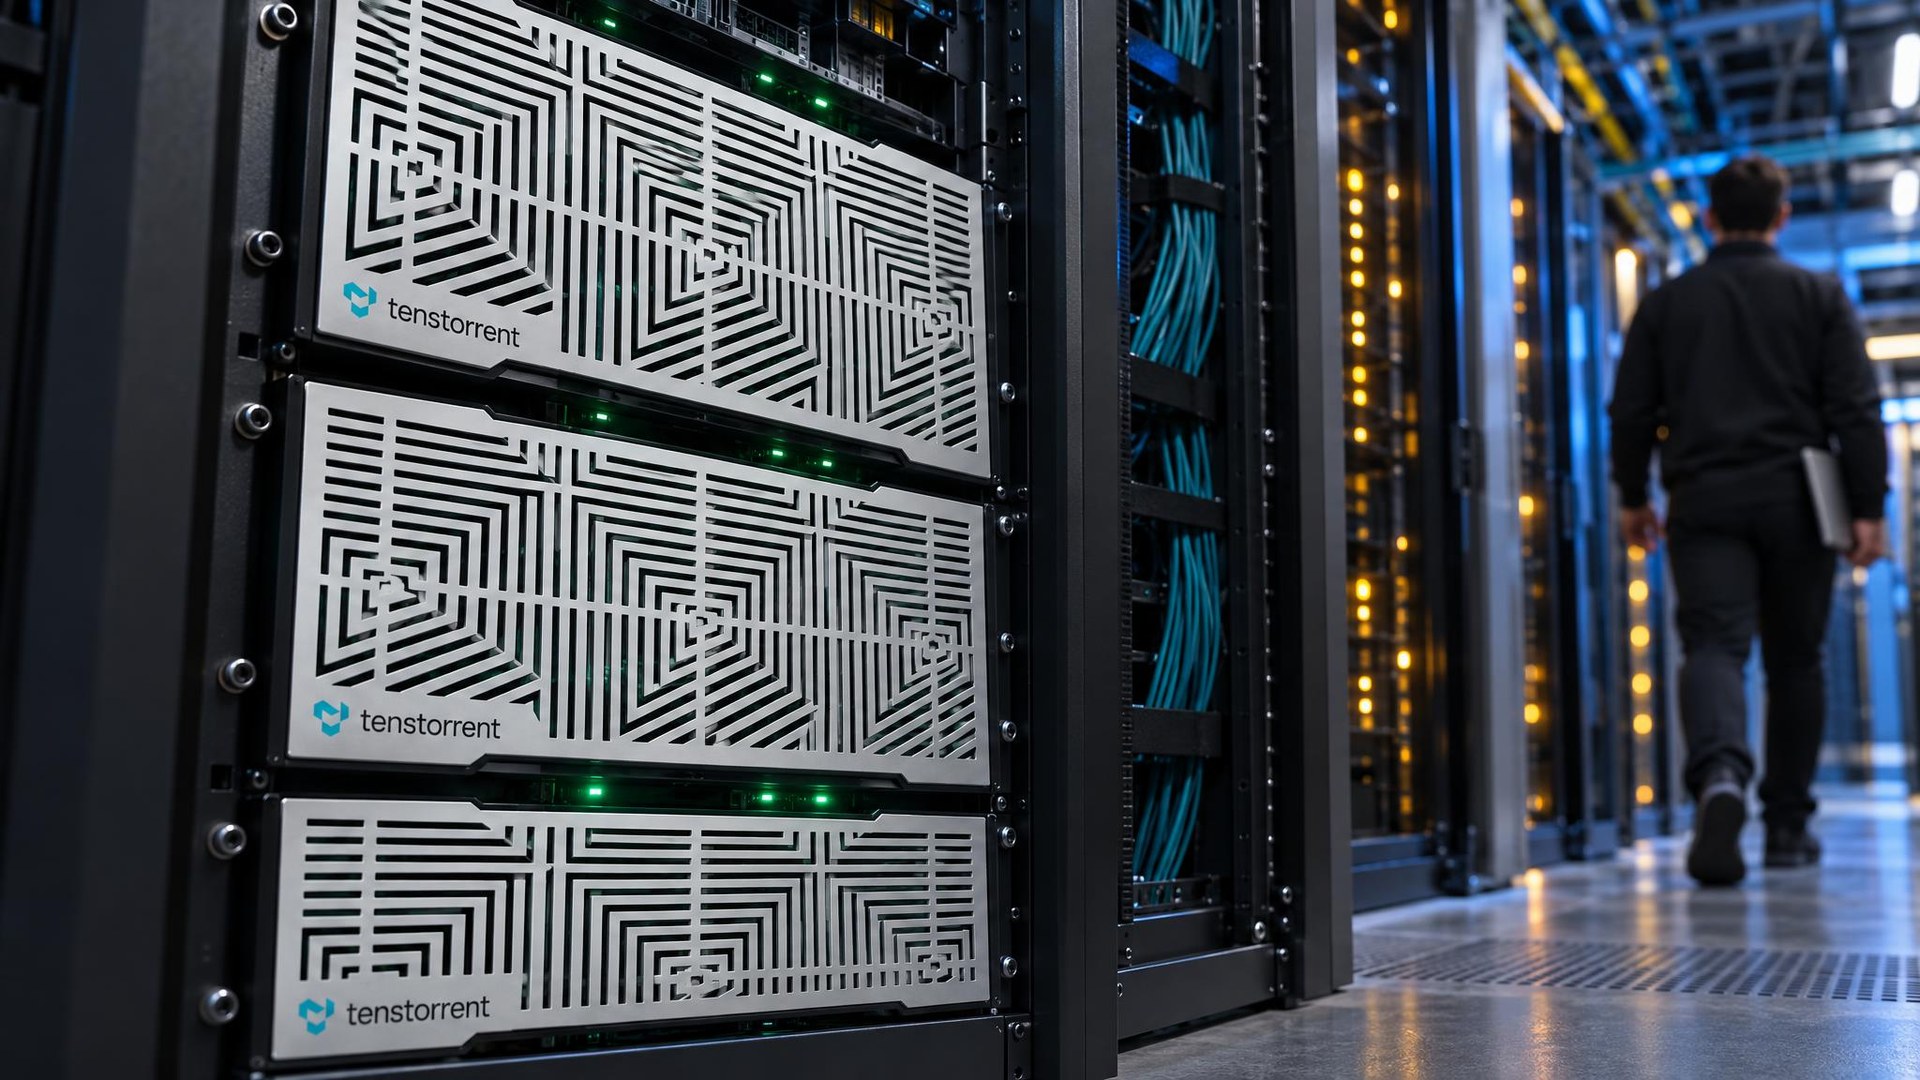
Tenstorrent and Smallest.ai announced a partnership on October 1, 2026, to deliver a production-grade, on-premises voice AI stack that runs Smallest.ai’s Lightning V2 real-time text-to-speech model natively on Tenstorrent Galaxy Blackhole servers.
Tenstorrent, an AI compute company, and Smallest.ai, an AI research lab building real-time voice AI infrastructure, said the joint stack is designed to reduce deployment costs while delivering the performance required for real-time voice applications. The companies said running Lightning V2 on the Blackhole architecture lets organizations operate real-time voice agents entirely on-prem with full data sovereignty, targeting high-volume, data-sensitive workloads across financial services, telecom, healthcare, and enterprise environments. Lightning V2 is available on Tenstorrent hardware immediately, with usage-based pricing and no upfront commitments.
“There shouldn’t need to be a choice between performance and cost – Tenstorrent has built efficient and scalable compute that reduces the cost of existing workflows and makes entirely new workloads practical,” said Amr Elashmawi, Vice President of Strategy & Business Development at Tenstorrent.
Galaxy Blackhole Hardware
The server platform named in the announcement is built around 32 Blackhole ASICs delivering 23 PFLOPS of Block FP8 compute, with 6.2 GB of on-chip SRAM at 2.9 PB/s and 1 TB of GDDR6 memory at 16 TB/s, according to Tenstorrent’s Galaxy specifications. Each ASIC connects through ten 400 GbE links for a 32 TB/s accelerator fabric, and systems scale out through up to 56 800 GbE QSFP-DD ports. The 6U air-cooled chassis pairs an AMD EPYC 9004 host processor with up to 576 GB of DDR5 memory, runs Ubuntu 22.04, draws 8 to 10 kW on average, and carries a list price of $160,000.
Reduced-Precision Design and Measured Results
The engineering behind the partnership is documented in a paper, “Rewriting TTS Inference Economics: Lightning V2 on Tenstorrent Achieves 4x Lower Cost Than NVIDIA L40S,” authored by Smallest.ai’s Ranjith M S, Senior AI Inference Performance Engineer; Chief Technology Officer Akshat Mandloi; and Chief Executive Officer Sudarshan Kamath. The paper was first submitted on March 24, 2026, and revised on April 7, 2026.
Ranjith, the paper’s first author, said in the announcement: “Tenstorrent’s architecture is fundamentally different from existing paradigms. Working with the NoC and larger SRAM, we unlocked 4x gains at a fraction of the cost of comparable GPU infrastructure, driving a structural shift in inference economics.”
The authors report that text-to-speech models are significantly more numerically fragile than large language models because they generate continuous waveforms through iterative refinement, so small numerical errors compound across denoising steps and surface as audible artifacts. Against that constraint, the paper reports that more than 95% of Lightning V2’s layers run at LoFi computational fidelity and more than 80% of the model deploys in BlockFloat8 without measurable degradation in audio quality. The authors also report a 4x compute reduction in the diffusion acoustic model, an 8x compute reduction in the neural vocoder, an approximately 2x reduction in model size, and a 1.8x reduction in memory transfer volume.
On output quality, the paper reports a DNSMOS perceptual score of 3.872 for an NVIDIA L40S baseline versus 3.801 on Tenstorrent’s P150, a 0.071 difference the authors describe as falling within the range of minor perceptual variation, and a normalized word error rate of 0.009 between the two systems’ outputs.
In single-device testing, the paper reports the L40S sustaining a concurrency of 3 at 300-millisecond latency against a listed device cost of $9,000, while the P150 and P100 each ran a concurrency of 1 at 250-millisecond latency at listed costs of $1,400 and $1,000, for reported cost gains of 2.6x and 3.6x respectively. Because Lightning V2 executes on a single chip without multi-chip parallelism or the QSFP interconnect, the P100 latency figure is carried over from measured P150 results, the paper notes.
At fleet scale, the authors model a workload of 550 simultaneous five-second TTS requests at full utilization. They calculate that sustaining it would require 11 L40S GPUs at roughly $100,000 in accelerator cost, versus 27 P100 accelerators at roughly $27,000 or 27 P150 accelerators at roughly $37,000, a 3-4x reduction in upfront cost in their modeled comparison.
The paper also reports that one heavily optimized layer of roughly 6 billion multiply-accumulate operations executes in about 60 microseconds on the L40S versus about 31 microseconds on the P150. The authors project that extending such kernel-level optimization across more layers could yield an 8-12x cost-normalized improvement over the L40S baseline, up from the current 3.6x system-level gain.
The authors frame native BlockFloat8 support as a hardware-cost dividing line: contemporary GPUs with that capability sit in the roughly $40,000 price class per device, they report, while Tenstorrent enables BlockFloat8 execution on hardware in the roughly $1,000 class, an order-of-magnitude difference in acquisition cost in their description.
Numerical Fragility and the PCC Case
The paper documents a debugging case study around the Pearson Correlation Coefficient, a standard numerical similarity metric. The authors report that outputs from the L40S and an AMD EPYC 7352 CPU showed an end-to-end coefficient of only 0.72 despite identical inputs, yet produced perceptually indistinguishable audio. In a separate instance, a layer whose coefficient rounded to 1.0 caused audible breakage that took more than a month to isolate. The authors conclude that conventional tensor-level similarity metrics are not reliable indicators of perceptual audio quality in TTS systems, and that end-to-end perceptual validation is necessary for reduced-precision deployments.
Limitations and Next Steps
The authors state that certain layers remain too numerically sensitive for reduced-fidelity or block floating-point execution without perceptual degradation, limiting full-model low-precision coverage, and that compiler and program configurations are not yet fully optimized.
In a September 28, 2026 technical post, Smallest.ai characterized Lightning V2 as the world’s first TTS model to deliver high-quality speech synthesis under joint BlockFloat8 quantization and reduced-precision arithmetic. The company said its newer Lightning V3 already surpasses V2 in quality and architectural efficiency, and that it plans to deploy Lightning V3 on Tenstorrent hardware with the same co-design principles, targeting similar or greater cost breakthroughs.
