

Researchers at the University of Illinois Urbana-Champaign have developed a learning method that helps robots improve task performance while maintaining stability. The approach combines reinforcement learning with control theory to provide stability guarantees and improve tracking performance by up to 15 percent compared with existing methods. The method, called contraction-aware reinforcement learning, is designed for robots with different forms of movement, including wheeled, flying, and six-legged platforms.
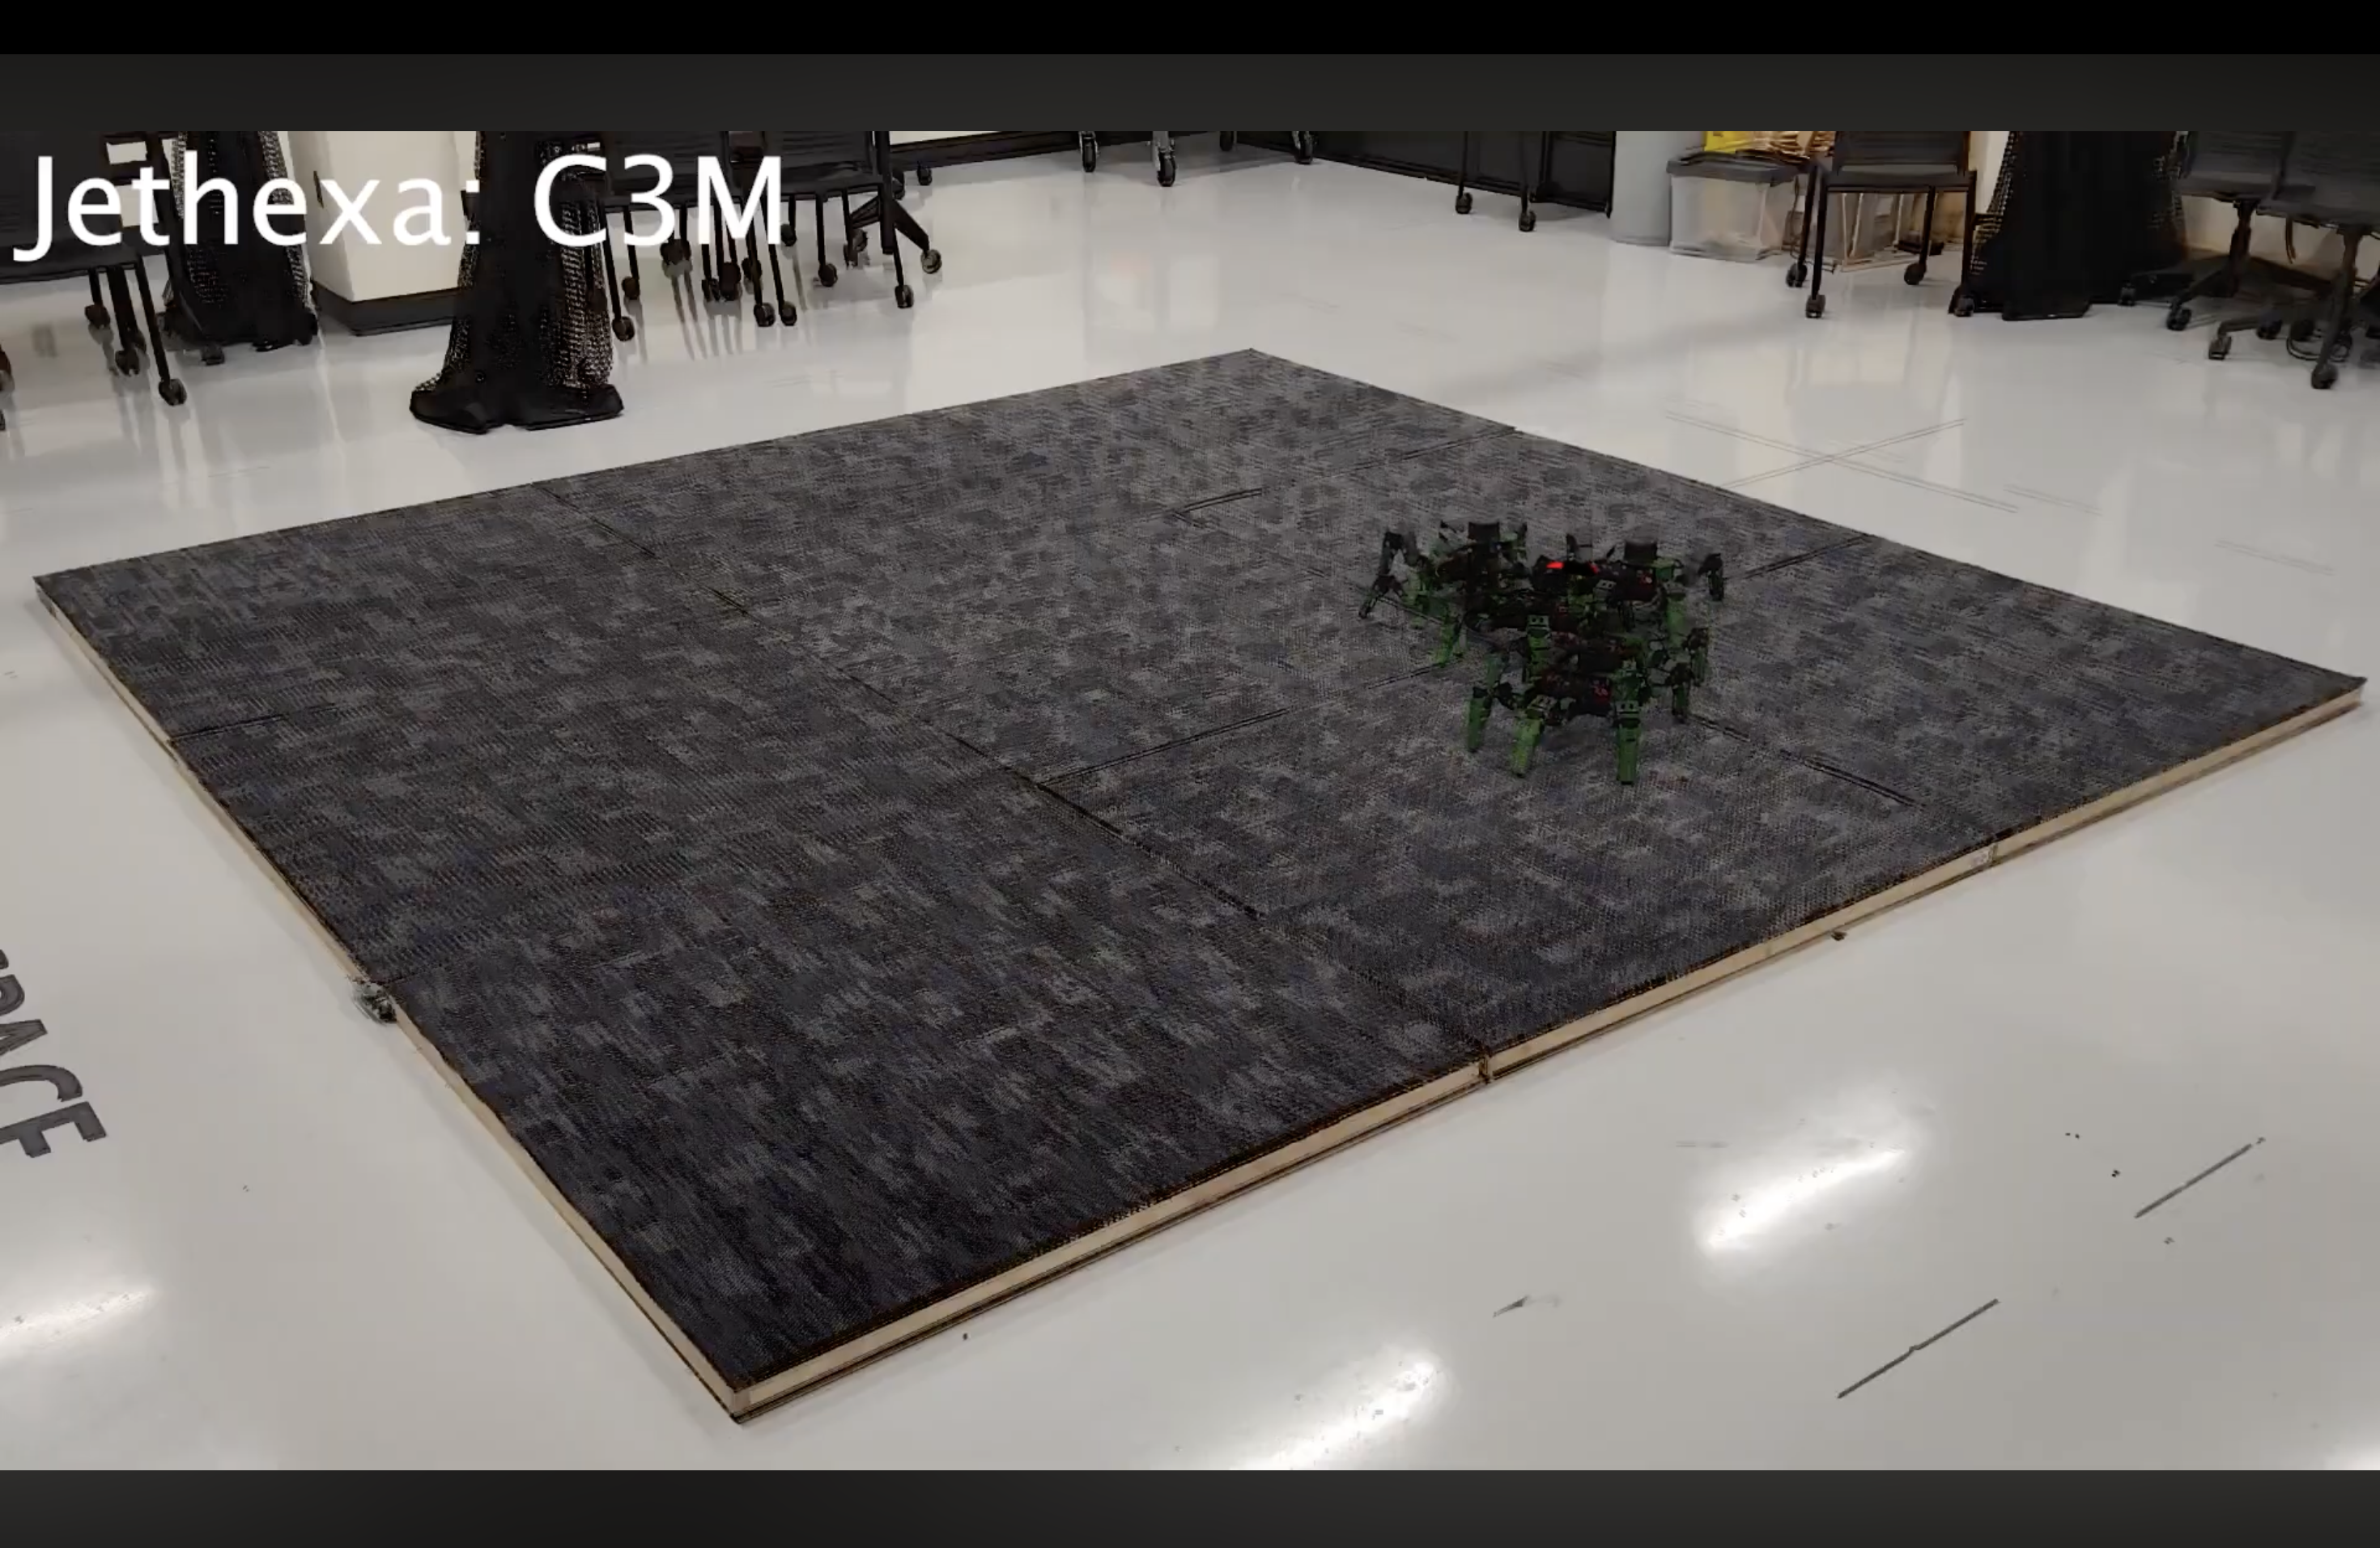
The researchers said the approach could make deploying learning-based robotic systems more practical by reducing the risk of instability and costly damage during operation.Robots learn stabilityThe reinforcement learning method helps robots follow desired paths while maintaining stability. Called Contraction-Aware Reinforcement Learning (CARL), the technique combines reinforcement learning with contraction theory to improve control performance and provide mathematical guarantees on how tracking errors behave.The researchers tested the method on three different robotic platforms: a wheeled TurboBot 3 Burger, a flapping aerial drone, and a six-legged Jethexa robot.
The experiments showed that CARL improved tracking performance by up to 15 percent compared with existing methods, including during tests on physical robots.Reinforcement learning allows robots to develop control strategies through repeated interactions with their environments. The system learns from feedback, adjusting its actions to improve performance and achieve a target objective.However, reinforcement learning does not inherently guarantee that a robot will remain stable while executing a learned policy.
A robot may learn an effective way
A robot may learn an effective way to complete a task but still exhibit unpredictable behavior or deviate excessively from its intended trajectory.CARL addresses this challenge by integrating reinforcement learning with contraction theory, a mathematical framework used to analyze the stability of dynamic systems. The approach allows reinforcement learning to serve as the robot’s main controller while providing limits on how much tracking errors can grow.According to the research team, small tracking errors may still occur, but the method establishes mathematical bounds on their magnitude.
This provides a way to combine the adaptability of learning-based control with the stability requirements of physical robotic systems.The approach aims to help robots achieve their objectives without allowing deviations from their intended behavior to become excessive.Learning reliable movementThe researchers first evaluated CARL in computer simulations before moving to physical experiments in an aerospace engineering flight laboratory.They tested the technique on three robots with different movement mechanisms: a wheeled TurboBot 3 Burger, a flapping aerial drone, and a six-legged Jethexa robot.
This allowed the team to examine how the control method performed across different types of robotic dynamics.A major challenge in transferring learned control strategies from simulations to physical machines is the sim-to-real gap. A robot’s actual physical properties may differ from the values used to train its controller in a simulated environment.For example, a simulation may represent a robot as weighing 1 kilogram (2.2 pounds), while the real machine weighs 1.2 kilograms (2.6 pounds).
Such discrepancies can affect how a robot responds
Such discrepancies can affect how a robot responds to control commands and follows a planned trajectory.The researchers reported that CARL handled these uncertainties more effectively than existing methods. Its improved tracking performance was observed not only in simulations but also during real-world testing, suggesting that the technique can maintain its advantages beyond computer-generated environments.The researchers identified wildfire management as one possible application for the technology.
Robots deployed in hazardous environments could help locate hotspots, gather information, or deliver supplies to first responders. In such situations, reliable movement and predictable control are important because unexpected deigned task.The researchers have made the method openly available, with implementation code published on GitHub
