

Introduction
Retrieval-augmented generation (RAG) answers questions using information retrievedfrom a set of documents. That document collection is called a corpus. A typical evaluationsends a well-written question to a tidy corpusand checks whether the retriever returns the correctpassage.
Production documentcollections rarely stay tidy.
Old pages remain searchable after a policy changes. Users type “warehuse” instead of “warehouse.” Optical character recognition (OCR), the software that extracts text from scans, may read “SSO” as “SS0.” A table can also be divided at a page boundary, separating a number from its label.
Each problemcan send the retriever to the wrong passage. The language modelthen receives incorrect or incomplete context, so even a well-written answer may be wrong.
In this article we will see a small retriever and fault injection, which means deliberately adding problemsto test how a system responds. I added an outdated policy page, an OCR character swap, a query typo, and a divided table.
Hey there, I’m Sara Nóbrega, an AI engineer with background in physics. If you’re working on similar problems or want feedback on applying these ideas, I collect my writing, re
👉 Read: 5 AI Skills That Will Keep Data Scientists Relevant in 2027 | Towards Data Science
The Toy Pipeline
A retrieversearches documents and returns the passages that appear most relevant to a question. RAG systems usually divide each document into smaller passages called chunksbefore indexing them for search.
This examplekeeps the retrieval method deliberately simple. It has 4 short documents and one scoring function. The function splits the query and each document into lowercase words, called tokens. It then gives a document 1 point for every query token found in that document. The document with the highest score wins.
DOCS = [Document("returns-2026", "Returns are accepted within 30 days.", "returns", "2026-02-01"),Document("plans", "The Enterprise plan includes SSO for employees.", "plans", "2026-01-10"),Document("crm", "CRM contact sync runs every five minutes.", "integrations", "2026-01-05"),Document("inventory", "Warehouse inventory sync runs every 15 minutes.", "inventory", "2026-01-12"),]def tokens(text: str) -> list[str]:return re.findall(r"[a-z0-9]+", text.lower())def score(query: str, text: str) -> float:query_tokens, doc_tokens = tokens(query), tokens(text)return sum(token in doc_tokens for token in query_tokens)Each Document stores an ID, its text, a topic, and the date it was updated. Production systems often use more complex matching methods. Exact token matching makes each failure easy to see, and the same input problems can affect those systems.
Stale documents that contradict each other
The returns policy changed from 60 days to 30 days at the start of 2026. The ingestion process copiesge without removing the old one
old_policy = Document("returns-2024", "Returns are accepted within 60 days.", "returns", "2024-08-01")contradictory_docs = [old_policy] + DOCSretrieve("How many days is the returns window?", contradictory_docs)# returns-2024Both pages receive the same token-overlap score because each contains “returns” and “days.” The retriever needs a rule for equal scores, known as a tiebreaker. Here it uses list order, so it returns the first page: the policy from 2024. A customer could be told they have 60 days to return an item when the current limit is 30.
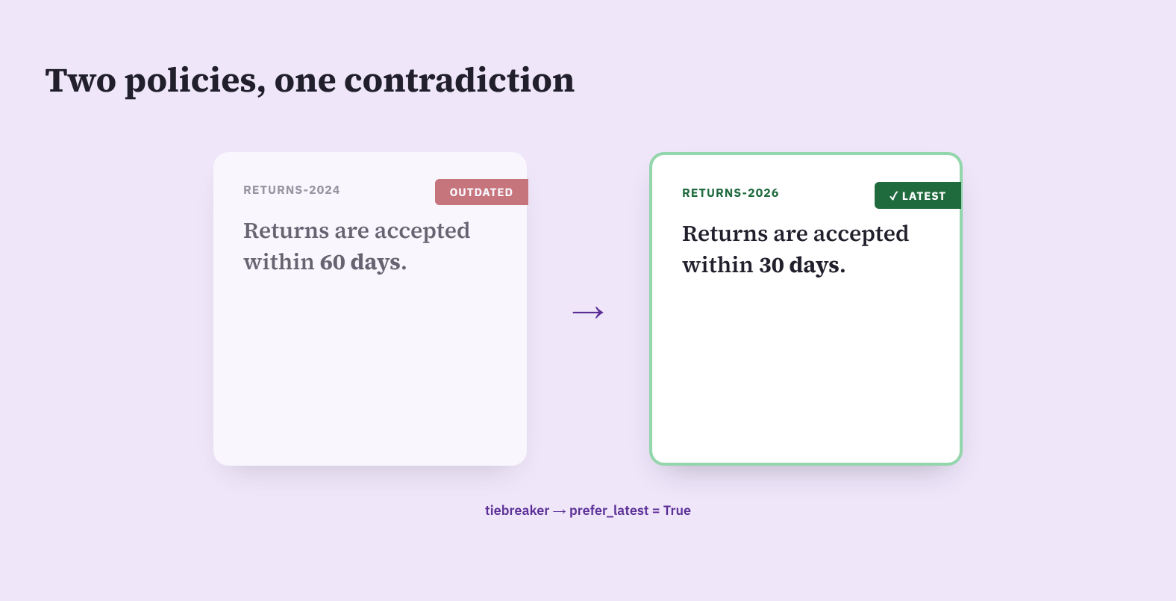
The correction adds a recency tiebreaker. When documents receive the same score, the retriever prefers the one with the later updated date.
retrieve("How many days is the returns window?", contradictory_docs, prefer_latest=True)# returns-2026This rule fits policies with a clear replacement date. Other collections may need an explicit status such as current or retired, especially when a newer document does not replace an older one.
OCR errors that hide the matching words
OCR converts scanned pages into searchable text. Similar-looking letters and numbers cause common extraction errors. The faulty OCR output changes “Enterprise” to “Enterpr1se” and “SSO” to “SS0.”
noisy_docs = [replace(doc, text=doc.text.replace("Enterprise", "Enterpr1se").replace("SSO", "SS0"))if doc.id == "plans" else doc for doc in DOCS]retrieve("Does Enterprise include SSO?", noisy_docs)# returns-2026The extractedtext contains enterpr1se and ss0, so the query tokens enterprise and sso each receive 0 points. All 4 documents tie at 0, and list order sends the returns policy back as the result.
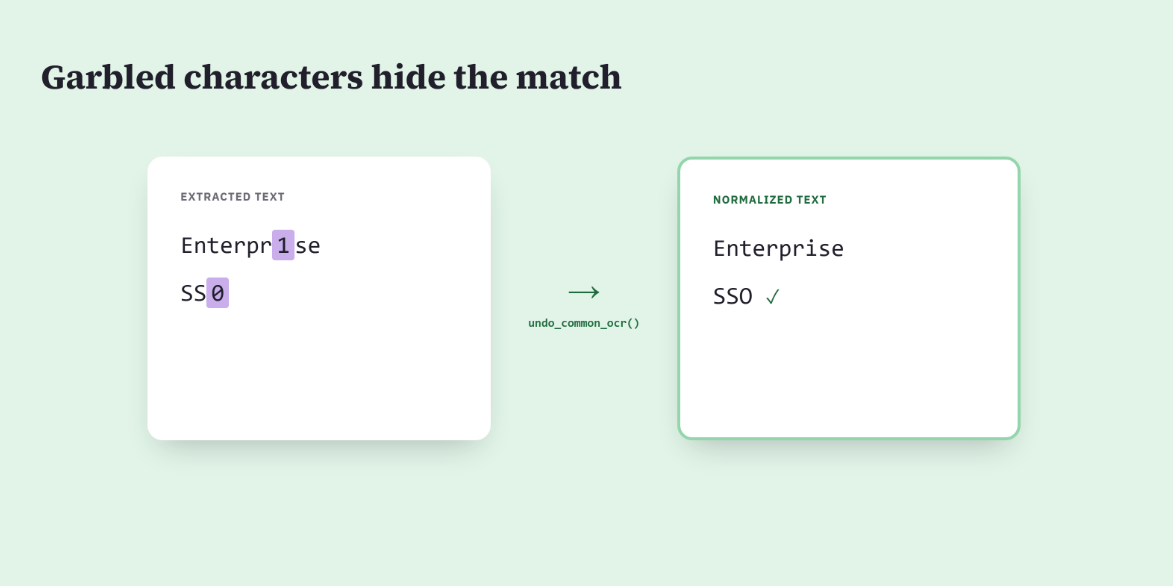
A normalization function corrects known OCR substitutions before tokenization. Applying it to both queries and documents gives the scorer consistent text.
def undo_common_ocr(text: str) -> str:return text.lower().translate(str.maketrans({"0": "o", "1": "i"}))retrieve("Does Enterprise include SSO?", noisy_docs, ocr=True)# plansProduction normalization rules need care. Converting every 0 to o, for example, could damage product codes or measurements. Build substitutions from errors found in your own extracted documents and limit them to fields where the change is safe.
A typo in the query
Users make spelling mistakes. “warehuse sync” is missing one letter from “warehouse sync,” and an exact token matcher treats the 2 words as unrelated.
retrieve("warehuse sync", DOCS)# crmThe misspelled token contributes 0 points. This leaves sync to determine the result. Both the CRM document and the warehouse inventory document contain it, so the tie goes to the CRM document because it appears first.
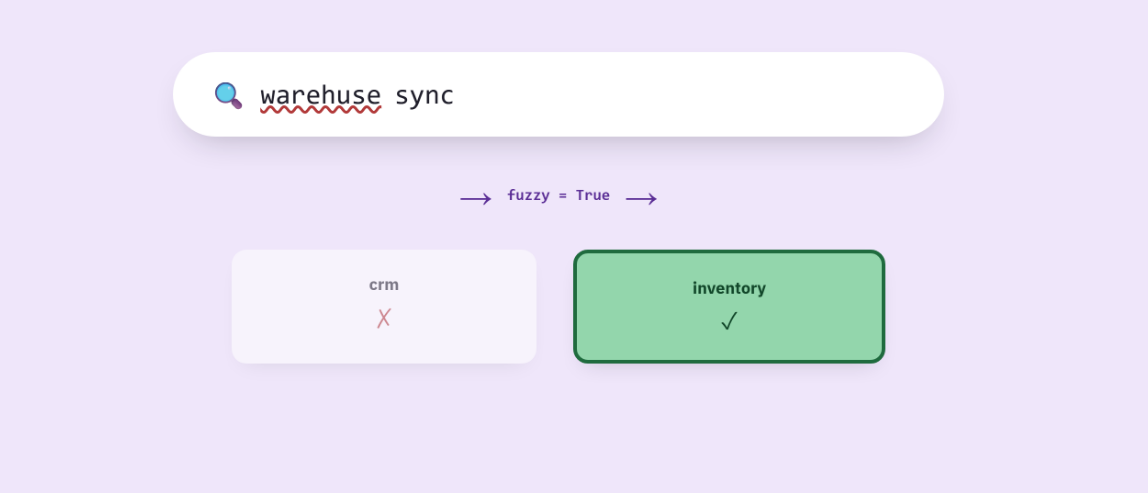
Fuzzy matching compares words by spelling similarity and gives close matches partial credit. With fuzzy matching enabled, warehuse is close enough to warehouse for the inventory document to score higher.
retrieve("warehuse sync", DOCS, fuzzy=True)# inventoryThe similarity threshold matters. Set it too low and unrelated words can match; set it too high and common typos still fail. Tests based on real queries provide better thresholds than a handful of invented spelling mistakes.
A table divided across a page boundary
Some PDF extraction tools create one chunk per page. If a table continues onto the next page, the first chunk may contain a row label while the second contains its value.
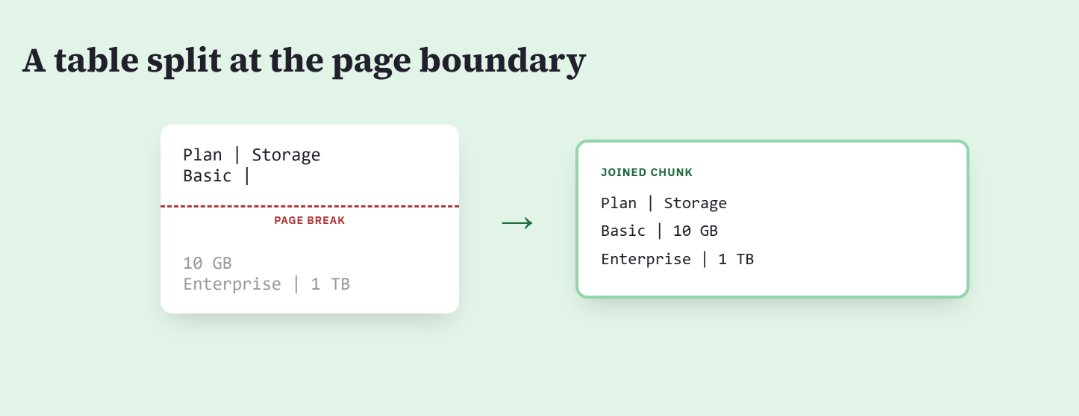
Image by Author | Claude Design.
The first chunk contains all 3 query tokens: basic, plan, and storage, so it ranks first. Its text ends after Basic |. The value, 10 GB, is in the next chunk and may never reach the language model.
raw_table = "Plan | StoragenBasic |<PAGE_BREAK>10 GBnEnterprise | 1 TB"table_pages = [Document(f"limits-p{i}", page, "limits", "2026-03-01")for i, page in enumerate(raw_table.split("<PAGE_BREAK>"), 1)]retrieve("Basic plan storage", table_pages)# limits-p1: "Plan | StoragenBasic |"This correction belongs in the ingestion process. Detect table fragments and join related pages before creating searchable chunks.
joined_text = " ".join(page.text for page in table_pages)joined_table = Document("limits-joined", joined_text, "limits", "2026-03-01")retrieve("Basic plan storage", [joined_table])# limits-joined: "Plan | Storage Basic | 10 GB Enterprise | 1 TB"Joining every pair of pages would create oversized chunks and mix unrelated text. Limit the rule to detected tables or carry enough neighboring content forward to preserve each row.
Test the evidence inside each result
The returned document ID confirms whichontains enough information to answer the question. The divided table demonstrates the difference: a chunk from the correct limits document could contain Basic and Storage while leaving 10 GB on the next page
Add an evidence check to each test. The check names the words or values that must appear in the retrieved text for the language model to produce a supported answer.
def assert_retrieval(result, expected_id: str, required_text: list[str]) -> None:assert result.id == expected_idresult_text = result.text.lower()assert all(text.lower() in result_text for text in required_text)The returns-policy test should require both the current document ID and the current value:
result = retrieve("How many days is the returns window?",contradictory_docs,prefer_latest=True,)assert_retrieval(result, "returns-2026", ["30 days"])The table test should require the row label and its value in the same retrieved chunk:
result = retrieve("Basic plan storage", [joined_table])assert_retrieval(result, "limits-joined", ["Basic", "10 GB"])These assertionsalso make failures easier to diagnose.
A wrong ID points to ranking or filtering. A correct ID with missing text points to extraction or chunking. A correct ID with the required evidence gives the generation step enoughs own evaluation
If your retriever returns several chunks, apply the same check to the combined text passed to the language model. The evaluated text will then match the context the model receives.
What the 4 tests catch
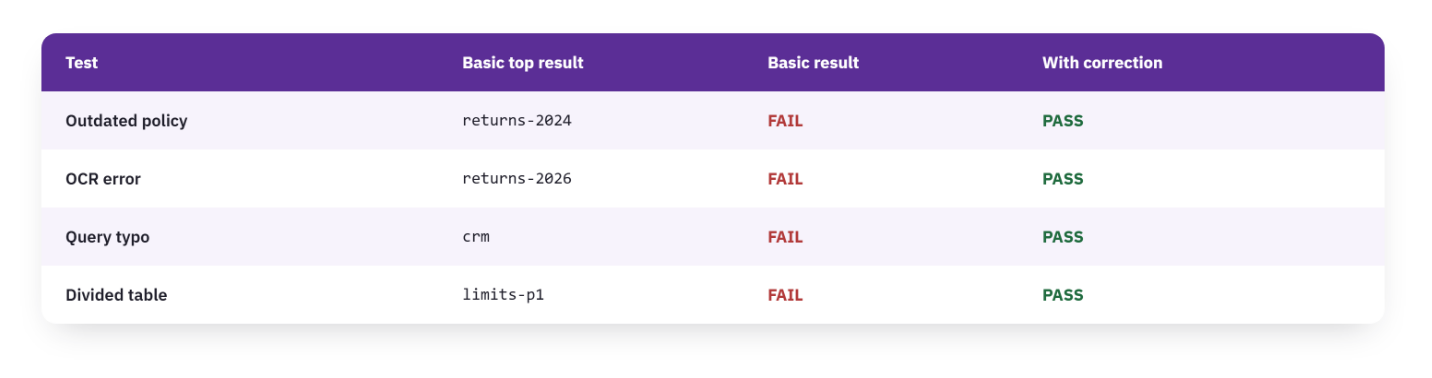
Running the 4 corruptedinputs against the basic retriever produces 4 failures. After the matching correction is enabled for each case, all 4 return the expected document.
-
use document dates to resolve a tie, normalize known OCR errors,
-
allow close spelling matches, and
-
preserve table rows during ingestion.
Each one addresses a different cause. The separate test results identify which protection is missing.
Run these testsalongside a standard relevance evaluation. Relevance tests measure whether retrieval works on expected inputs. Fault-injection tests measure whether it still works after a realistic defect is added to the query or document collection.
The 4 casesare a starting testset. When production returns the wrong document, add a regression test: a repeatable check that confirms the bug stays fixed after later code changes.
Thanks for reading!
My name is Sara Nóbrega and I’m an AI engineer with background in physics.
